FUSE Worker Guidance
Buildbarn supports a lot of different ways of setting up your build environment, with virtual file systems, inside of containers, running on bare-metal, etc. As a consequence it might be a bit difficult to understand when you should use which settings.
In this article I'm giving some general guidance for how to configure FUSE-based workers in a Linux container-based environment (such as Kubernetes). This might not cover your exact environment, but some of the advice generalizes to other scenarios as well.
Worker/runner setup
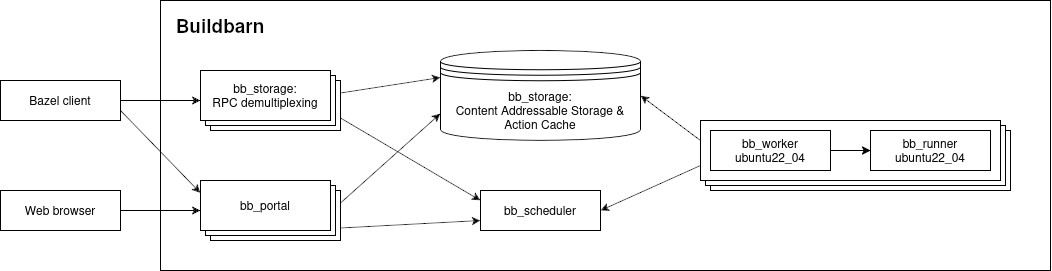
The first thing to understand is the worker/runner separation. The worker is a process which is responsible for setting up build directories for actions and has all the communication setup required to talk with the scheduler and storage, while the runner is responsible for actually executing the actions and reporting back their results to the worker. As the worker keeps track of cached inputs, directories, etc. you want to set up your build system such that you have one worker per node, but multiple runners for that worker. Each runner should have its own container, its own independent resource requests and limits, and ideally be pinned to its own cpuset.
This greatly reduces your actions' ability to interfere with each other. Without this resource-level separation, different actions share the same pool of resources and unlucky actions may be starved out by neighbouring actions.
Content Addressable Storage configuration
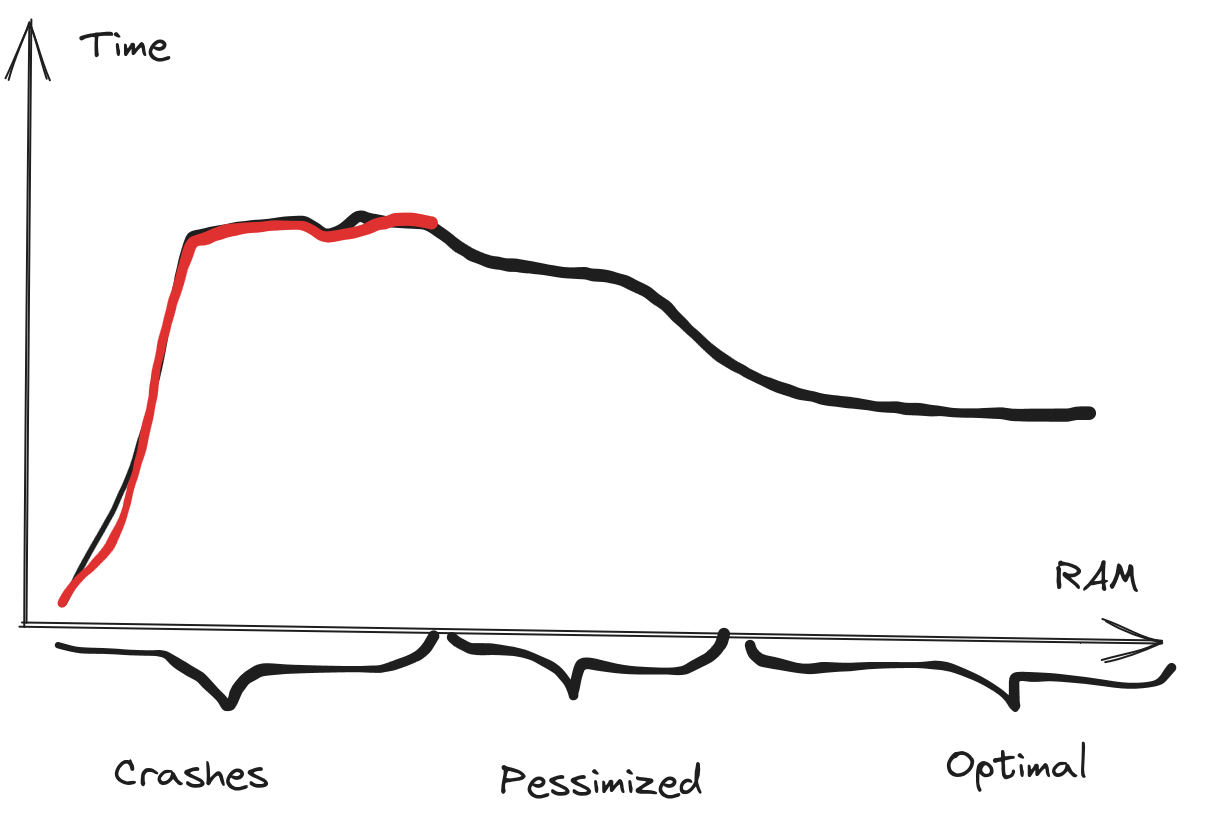
The Chunk Storage (CS) of the Content Addressable Storage (CAS) contains the content of the files. In a virtual file system where the content is fetched on demand, it's important that this gets cached properly. Failure to configure this causes the worker to perform a network request to storage every time the worker needs to read from the file system. While this works, it has unacceptable performance characteristics.
There are multiple layers of caches that can be configured here.
Local readCaching copy of the Chunk Storage itself
Have a local on-disk copy of the CS that can be used to prevent us from downloading the same chunk over and over again. While this could technically be added for the Chunk Mapping Storage (CMS), this isn't recommended as the CMS is far smaller and can be kept in its parsed form in memory instead.
contentAddressableStorage: {
    chunkStorage: {
        readCaching: {
            slow: upstreamChunkStorage,
            fast: {
                'local': {...}
            },
            replicator: { deduplicating: { 'local': {} } },
        },
        ...
    },
    ...
}
In-memory caches of parsed objects
The CAS offers caching configuration for three objects that are referenced often by runners.
The chunkCache stores the integrity-verified and decoded content of
the chunks. Chunks can be fairly big so this cache should be sized to
fit your hot set. A reasonable value would be something akin to the
equivalent of 10% ram.
The chunkMappingCache stores the parsed chunk mapping with
precalculated cumulative offsets for binary searching positions from
chunk mappings. Chunk mappings are fairly small (typically < 2 KiB but
may be megabytes for very large files) and among the files of an action
most of them will not have a chunk mapping (single chunk files). A
reasonable value would be 1000 entries per runner. This would correspond
to allowing each runner to read up to 1000 large files.
The cdcParameterCache is a cache for upstream CDC parameters. It needs
an entry per upstream instance name in use, so it can be positively
tiny. It prevents each interaction with a digest from having to look up
its CDC parameters remotely.
Additionally, the worker itself defines a directory cache, which is an in-memory cache of parsed directory objects. This is also important as parsing a proto message to a directory object is a heavy operation to perform whenever interacting with a directory.
Build Directories
The worker is configured with build directories. This configuration tells the worker how to produce the build directories for actions. As we're using a virtual file system we have the opportunity here to create one build directory per runner at no appreciable cost. Mount only the specific build directory belonging to the specific runner.
This further increases isolation as parallel actions are no longer able to interfere with each other's build directories and also allows the kernel to treat each build directory as its own resource.
# an array, use one per runner
buildDirectories: [
    {
        virtual: { ... },
        # also an array, use a single runner with concurrency 1
        runners: [{ concurrency: 1, ... }],
    },
    ...
],
Tune the kernel parameters for the FUSE mount
The kernel has several parameters for how it should treat a FUSE file system. Relying on the kernel defaults may give suboptimal results. The above setup does significantly increase the throughput by making a directory per runner, but especially for large runners you may want to tune the following:
linux_backing_dev_info_tunables
Controls allowances of the FUSE file system. See kernel documentation and Buildbarn documentation
Recommended values are:
{
    ...
    linuxBackingDevInfoTunables: {
        "max_ratio": "10",
        "strict_limit": "0"
    }
}
Which increases the FUSE mount's quota of the kernel write-back cache.
NOTE: To configure this in many Kubernetes environments you must mount
/sys into the worker pod using a hostPath volume, as Kubernetes may
make the /sys file system read-only depending on which sidecars your
pod has.
Maximum background tasks
The default maximum number of background tasks is 12. These requests are typically page-cache readahead and asynchronous writebacks. As soon as you have 12 or more concurrent requests of this type to the file system, the kernel will start to block background requests to keep the file system responsive.
Additionally, when the queue is above 3/4 of this value, the kernel will mark the BDI as congested, which throttles other asynchronous requests.
Increase this to a more reasonable value, such as 128 per runner vCPU.
{
    ...
    maximumBackgroundTasks: 128*cpus_per_runner
}